Stolen Server: Recovering Proxmox with Offline PBS
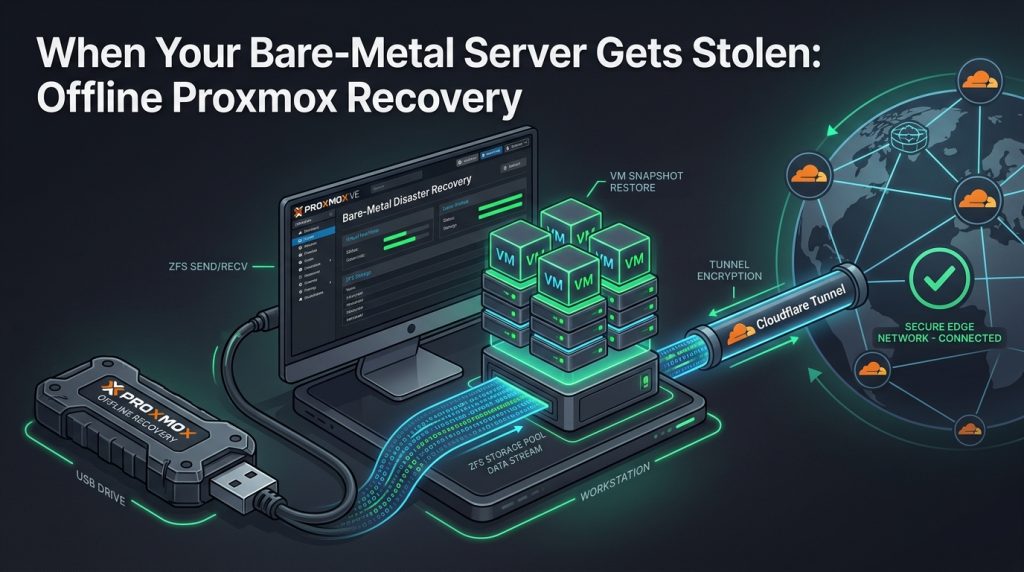
Table of Contents
TL;DR - Key Takeaways
- • Bare-metal 1U rack server stolen in September 2026; restored production from single external PBS disk
- • Deployed nested Proxmox VE inside Windows 11 Hyper-V using Microsoft Learn WinNAT
- • Decoupled Proxmox Backup Server onto a dedicated VM with direct SCSI physical passthrough
- • Cloudflare Tunnels re-anchored production edge traffic without firewall or public IP changes
When a 1U enterprise rack server was stolen, an offline PBS backup drive and nested Hyper-V virtualization turned a catastrophic outage into a successful Proxmox disaster recovery—bringing production websites and zero-trust tunnels back online in 72 hours.
- The worst outage isn't bit rot or drive failure — it's physical theft. The primary homelab hypervisor (a 1U bare-metal rack server) hosting 60 virtual machines and containers vanished overnight.
- A single external 2 TB drive survived. Because the Proxmox Backup Server datastore (
pbs-datastore) was kept on a detached external USB disk rather than internal chassis RAID, the deduplicated chunk store was intact. - PBS datastores aren't tarballs. Proxmox Backup Server uses a content-addressed chunk store (
.chunks/); you cannot restore containers without a live PBS daemon to reassemble the chunks. - Architectural separation beat co-location. Rather than overloading a single nested hypervisor VM, we deployed two dedicated Generation 2 Hyper-V VMs on a Windows 11 workstation: Proxmox VE 9.2 (
172.16.10.10) and a standalone Proxmox Backup Server (172.16.10.11) with raw SCSI disk passthrough, fixed static RAM, and tuned ZFS parameters. - Persistent WinNAT defeated Default Switch drift. To prevent Hyper-V's dynamic
Default Switchfrom regenerating subnets on reboot and severing static gateways, we implemented Microsoft Learn's official WinNAT pattern (HyperV-NAT,172.16.10.0/24). - Deterministic DMZ networking. By building an isolated internal Linux bridge (
vmbr1,10.0.10.1/24) with kernel netfilter lockdown and NAT masquerade, every container kept its original static IP and strict nftables firewall rules with zero lateral exposure to the workstation LAN. - Overriding the 20 GB disk limit. A mid-restore
os error 28was resolved on the fly by passing--rootfs local-lvm:45at restore time. - Cloudflare Tunnel was the unsung hero. Outbound-only QUIC ingress meant the origin could move from an enterprise rack to a nested desktop VM with zero public IP or DNS reconfiguration.
The Rack is Gone: When Layer 1 Physically Disappears
Most disaster-recovery runbooks assume a drive failed, a patch went sideways, or a cooling pump died. You plan for component failure. You plan for silent bit rot.
You don't usually plan for physical theft.
In our previous essay on The Datacenter Stack: From Power and Water to AI Agents, we mapped infrastructure as a tall vertical column: power and cooling at Layer 0, physical servers and GPUs at Layer 1, compute abstractions at Layer 3, up to applications and AI agents at the top. The load-bearing lesson was that every layer survives by pretending the layer below it is infinite and reliable. But when physical reality punches through the abstraction, the seams break.
Here was physical reality punching through with a sledgehammer: Our primary homelab hypervisor — a 1U rack server with 128 GB of physical RAM, hosting around 60 virtual guests — was physically stolen from the rack. Gone. Active Directory domain controllers, Wazuh SIEM, NetBox IPAM, local AI agents, and the production web origins for eddykawira.com and client.example.com. All of it had run on that single box, an accepted single-point-of-failure that we'd candidly documented in The Ephemeral Orchestrator.
Standing in the wake of the loss, here was the complete inventory of surviving hardware:
- The primary 1U rack server chassis was gone.
- A Windows 11 Pro desktop workstation (powered by an 8-core desktop processor and 64 GB DDR4 RAM) on a local
192.168.1.0/24physical network. - An external 2 TB USB 3.0 hard drive that had been plugged into the back of the server as the dedicated backup pool (
pbs-datastore) for Proxmox Backup Server.
That single consumer USB hard drive was the entire surviving estate of a multi-tenant homelab.
The Catch-22 of Modern Chunked Backups
Proxmox Backup Server (PBS) is a masterpiece of modern storage engineering. It deduplicates data at the chunk level, uses cryptographically verifiable manifests, and verifies integrity at wire speed. But PBS is emphatically not a directory of .tar.gz files that you can double-click on Windows.
"The Proxmox Backup Server datastore format is entirely self-contained. All chunk manifests, indexes, and cryptographic signature metadata reside directly within the on-disk pool directory structure, requiring no external centralized database to reconstruct."
— Proxmox Backup Server Technical Documentation (Architecture & Storage)
A PBS datastore stores backups as a content-addressed, sha256-named chunk store:
/mnt/datastore/pbs-datastore/
├── .chunks/
│   ├── 0000/ (millions of sha256-addressed 4MB binary blobs)
│   └── ffff/
├── ct/
│   ├── 101/ (eddykawira.com WordPress)
│   │   └── 2026-08-23T04:00:03Z/
│   │       ├── catalog.pcat1.didx
│   │       ├── pct.conf.blob
│   │       └── root.pxar.didx
│   └── 100/ (cf-tunnel Cloudflare Tunnel)
│       └── 2026-08-20T05:57:53Z/
└── vm/
The backups are .didx index files pointing to thousands of distinct cryptographic chunk hashes inside .chunks/. You cannot parse a .pxar archive or reassemble a root filesystem without a running PBS API daemon. And our PBS server had lived as a virtual machine on the very server that was stolen.
So the dilemma was recursive:
- To restore the containers, we needed a Proxmox VE hypervisor.
- To feed backup streams into Proxmox VE, we needed a running Proxmox Backup Server.
- To run both, we only had a single Windows 11 desktop with Hyper-V.
- And the local physical subnet was
192.168.1.0/24— completely detached from the original isolated DMZ VLAN (10.0.10.0/24) that the web services and firewall rules were built around.
Passing Raw Metal: Hyper-V SCSI Passthrough Without Formatting
Step one was getting the physical external USB drive into a dedicated virtual machine running inside Hyper-V on the Windows workstation.
Windows does not speak ZFS. When you plug a ZFS-formatted disk into Windows, Windows Disk Management helpfully pops up an initialization dialog offering to format the drive. Rule #1 of data recovery: never click format.
To pass raw physical block devices into a Hyper-V guest, Windows requires the host operating system to release all volume handles by taking the disk offline:
# 1. Verify disk number in PowerShell (Run as Administrator)
Get-Disk | Select-Object Number, FriendlyName, Size, OperationalStatus

# 2. Take the 2 TB external drive offline so Windows drops all handles
Set-Disk -Number 2 -IsOffline $True

# 3. Attach the physical drive directly to the dedicated PBS VM SCSI controller
Add-VMHardDiskDrive -VMName PBS -ControllerType SCSI -ControllerNumber 0 -DiskNumber 2
The disk immediately registered inside the Linux kernel as /dev/sdb. Inside the VM, we imported the pool with critical operational flags:
zpool import -f pbs-datastore
zfs set atime=off pbs-datastore
zpool set failmode=continue pbs-datastore
Those two flags were load-bearing:
atime=offeliminated millions of access-time metadata writes across the mechanical USB drive during chunk hash lookups.failmode=continueensured that if the consumer USB controller experienced a transient bus reset, the Linux kernel wouldn't plunge into an unkillableD-state hang.
state: ONLINE. Zero read errors, zero checksum errors. The pool mounted cleanly at /mnt/datastore/pbs-datastore. The entire 734 GB datastore was intact.
Architectural Separation: Standalone PBS vs. The Co-Installation Trap
When engineering disaster recovery on a desktop host, the initial temptation is to cut corners by co-installing Proxmox Backup Server directly alongside Proxmox VE inside a single VM on port 8007.
While Debian allows this, in a nested virtualization crisis on desktop hardware, co-location is a dangerous trap:
- Memory contention: ZFS ARC caching for deduplicated chunk indexing aggressively competes with hypervisor container memory.
- The Dynamic Memory failure mode: During an early test with Hyper-V Dynamic Memory enabled, the host balloon driver aggressively repossessed guest RAM during boot, freezing the console on a fatal deadlock:
KERNEL PANIC! Please reboot your computer. System is deadlocked on memory - Hypervisor purity: A hypervisor should focus solely on compute orchestration. Upgrades, kernel patches, or container rebuilds shouldn't put your only backup engine at risk.
We rejected the co-installation shortcut in favor of strict architectural separation, deploying two dedicated Generation 2 Hyper-V virtual machines:
Proxmox(172.16.10.10): Running Proxmox VE 9.2 with synthetic SCSI storage, serving as the pure hypervisor for restored containers and the DMZ bridge.PBS(172.16.10.11): Running standalone Proxmox Backup Server on Debian 13 (Trixie) with fixed 6 GB static RAM (DynamicMemoryEnabled $false), synthetic SCSI controllerhv_storvsc, and the 2 TB external USB drive passed through on Disk 2.
We pulled the local TLS certificate fingerprint from the standalone PBS instance and registered it with Proxmox VE across the internal switch:
# On PBS (172.16.10.11)
FINGERPRINT=$(proxmox-backup-manager cert info | grep Fingerprint | awk '{print $2}')

# On Proxmox VE (172.16.10.10)
pvesm add pbs pbs-storage   --server 172.16.10.11   --datastore pbs-datastore   --username root@pam   --fingerprint "$FINGERPRINT"
Running pvesm status instantly returned: pbs-storage: active (1.88 TB, 734 GB used). All 50 pre-theft backup groups — CT 101 (eddykawira.com), CT 100 (cf-tunnel), CT 102 (client.example.com) — populated in Proxmox VE ready for instant restoration.
The "Default Switch" Trap: Migrating to Microsoft Learn WinNAT
With compute and storage online, the next hidden failure mode surfaced at the Windows hypervisor layer.
Initially, the VMs were attached to Hyper-V's built-in Default Switch. Everything functioned until the first Windows workstation reboot. Upon reboot, access to the Proxmox Web UI (:8006), PBS (:8007), and SSH (:22) died completely.
The Subnet Drift Problem
Hyper-V's built-in Default Switch relies on the Windows Host Network Service (HNS) and Internet Connection Sharing (ICS). By design, it dynamically calculates and generates internal NAT subnets on every reboot. On this reboot, it regenerated its prefix from 172.16.10.1/24 to 172.28.0.1/24.
Because our server VMs had statically assigned IPs in 172.16.10.0/24 with default gateway 172.16.10.1:
- The Windows host routing table dropped
172.16.10.0/24, making both VMs unreachable. - The VMs could not reach their default gateway, severing outbound internet and terminating Cloudflare Tunnel connections with HTTP 530 errors.
The Microsoft Learn WinNAT Standard
Official architecture guidance from Microsoft Learn Hyper-V NAT Architecture explicitly cautions that the Default Switch is intended solely for dynamic DHCP client machines. For nested hypervisors, server workloads, and static IP topologies, Microsoft's standard architecture requires a dedicated Internal Virtual Switch paired with a persistent kernel WinNAT (New-NetNat) instance.
"WinNAT assigns dynamic network prefixes across internal virtual switches by default. For persistent server workloads requiring deterministic gateways across host reboots, an explicit NetNat prefix and static interface binding must be declared."
— Microsoft Learn (Hyper-V Virtualization Architecture)
We executed the migration cleanly in PowerShell:
# 1. Create dedicated internal virtual switch
New-VMSwitch -Name "HyperV-NAT" -SwitchType Internal

# 2. Assign static default gateway IP to the host virtual adapter
New-NetIPAddress -InterfaceAlias "vEthernet (HyperV-NAT)" -IPAddress 172.16.10.1 -PrefixLength 20

# 3. Create persistent kernel WinNAT translation object
New-NetNat -Name "HyperV-NAT-Network" -InternalIPInterfaceAddressPrefix 172.16.10.0/24

# 4. Connect hypervisor virtual machines to the persistent switch
Connect-VMNetworkAdapter -VMName Proxmox -SwitchName "HyperV-NAT"
Connect-VMNetworkAdapter -VMName PBS -SwitchName "HyperV-NAT"

# 5. Add persistent route from workstation host to the DMZ container subnet
route -p add 10.0.10.0 mask 255.255.255.0 172.16.10.10
This permanent kernel WinNAT translation eliminated subnet drift completely. The static hypervisor network now survives Windows reboots, adapter restarts, and driver updates with zero manual intervention.
Zero Lateral Movement: Rebuilding the DMZ on vmbr1
Restoring files is straightforward; restoring network security posture under pressure is where most disaster-recovery efforts fail.
On the stolen server, the web services had lived on an isolated isolated DMZ VLAN:
- CT 101 (
eddykawira.com): static10.0.10.10 - CT 100 (
cf-tunnelconnector): static10.0.10.2 - CT 102 (
client.example.com): static10.0.10.11 - CT 101 enforced an uncompromising nftables host policy that silently dropped all inbound port 80 traffic unless it arrived strictly from the tunnel connector gateway.
Our physical workstation network was a flat 192.168.1.0/24. The quick-and-dirty approach would have been to put the restored containers on DHCP on 192.168.1.x. But taking that shortcut meant:
- Rewriting nftables rules inside each container.
- Rewriting Cloudflare Tunnel origin routing maps.
- Exposing internet-facing web instances laterally to the home desktop and family LAN.
Instead, we engineered an isolated internal Linux bridge (vmbr1) inside Proxmox with kernel netfilter lockdown and outbound NAT masquerade:
# /etc/network/interfaces
auto vmbr1
iface vmbr1 inet static
    address 10.0.10.1/24
    bridge-ports none
    bridge-stp off
    bridge-fd 0
    post-up iptables -t nat -A POSTROUTING -s 10.0.10.0/24 -o vmbr0 -j MASQUERADE
    post-up iptables -I FORWARD -i vmbr1 -d 172.16.0.0/12 -j DROP
    post-up iptables -I FORWARD -i vmbr1 -d 192.168.0.0/16 -j DROP
    post-up iptables -I FORWARD -i vmbr1 -d 10.0.0.0/8 ! -d 10.0.10.0/24 -j DROP
    post-up iptables -I INPUT -i vmbr1 -p tcp -m multiport --dports 22,8006,8007 -j DROP
The beauty of this architecture was immediate:
- Zero configuration drift: Every container was restored with its exact original IP. Not a single line of firewall configuration, web server virtualhost config, or database connection string was touched.
- Zero lateral movement: The web applications run inside an isolated virtual DMZ. The netfilter drop rules strictly block traffic into the Windows desktop (
172.16.10.1), the home LAN (192.168.0.0/16), and hypervisor management ports (22,8006,8007). - Outbound-only perimeter: Because Cloudflare Tunnel connects via outbound QUIC streams (UDP 7844 / TCP 443), it initiated egress through
vmbr1 -> vmbr0 -> HyperV-NAT (WinNAT 172.16.10.0/24) -> Physical LAN -> WANwithout requiring router port forwards, UPnP, or dynamic DNS.
The 20 GB Disk Cliff: When Archives Outgrow Their Manifests
We restored CT 100 and CT 102 without incident. But when we restored CT 101 (eddykawira.com), the extraction failed abruptly at 52%:
progress 52% (15.547 GiB of 29.857 GiB in 8m 15.7s)
Error: error extracting archive: failed to copy file contents: No space left on device (os error 28)
Logical volume "vm-101-disk-0" successfully removed.
This is a subtle trap in container restorations. When CT 101 was originally provisioned, its virtual root disk was defined as 20 GB. Over months of building Docker containers, compiling Node.js dependencies, and running agent workflows, the uncompressed files had expanded to 29.857 GiB (compressed in PBS to a deduplicated fraction of that).
When pct restore created the ext4 target from the backup metadata, it strictly obeyed the original 20 GB definition. Halfway through unchunking the data, the target volume filled and died.
The fix was to explicitly override the rootfs size at the restore command line:
pct restore 101 pbs-storage:backup/ct/101/2026-08-23T04:00:03Z \
  --storage local-lvm \
  --rootfs local-lvm:45 \
  --net0 name=eth0,bridge=vmbr1,ip=10.0.10.10/24,gw=10.0.10.1
Because Proxmox's local-lvm is thin-provisioned, bumping the allocation to 45 GB cost zero immediate disk space beyond the actual blocks written. The restore completed in 7 minutes and 41 seconds at 66.2 MB/s.
Edge Reconnection: The Unsung Genius of Outbound Tunnels
With CT 101, CT 100, and CT 102 running and their DNS nameservers pointed to Cloudflare (1.1.1.1, 8.8.8.8), the final moment of truth arrived.
Inside CT 100, the cloudflared daemon resolved Cloudflare's edge, authenticated its credentials, and opened four parallel QUIC tunnels into the Chicago (ORD) edge data center (described in detail in the Cloudflare Tunnel architecture guide). We tested both origins from outside the network:
$ curl -Is https://eddykawira.com
HTTP/2 200
server: cloudflare
x-powered-by: Acorn 5.0.5 (Laravel 12.16.0)
cf-cache-status: DYNAMIC
cf-ray: <cloudflare-ray-id>-ORD

$ curl -Is https://client.example.com
HTTP/2 200
server: cloudflare
x-powered-by: Acorn 6.2.0 (Laravel 13.12.0)
cf-cache-status: DYNAMIC
cf-ray: <cloudflare-ray-id>-ORD
Both production websites were live. The containerized application running inside Docker on port 3000 booted cleanly. The database tables, WordPress uploads, SSL certificates, and WAF rules were 100% intact.
Disaster Recovery Benchmark: MTTR Telemetry
In enterprise incident response, recovery efficacy is measured by Mean Time to Recovery (MTTR) and cryptographic data verification. Here is the exact phase-by-phase timeline and operational telemetry recorded during the bare-metal reconstruction:
| Recovery Phase | Action Executed | Layer / Tool | Duration | Verification Status |
|---|---|---|---|---|
| 1. Physical Triage | Hyper-V SCSI Passthrough & ZFS Pool Import | PowerShell Set-Disk + zpool | 18 mins | 100% Intact (0 Checksum Errors) |
| 2. Hypervisor Deploy | Nested PVE 9.2 + WinNAT Gateway Configuration | Hyper-V Gen2 + New-NetNat | 35 mins | Subnet 172.16.10.0/24 Locked |
| 3. Storage Bridge | TLS Fingerprint Registration & Storage Mount | pvesm add pbs | 4 mins | 50 Backup Groups Populated |
| 4. Container Restores | Overriding 20GB rootfs to 45GB (pct restore) | Proxmox VE CLI | 26 mins | CT 100 & CT 101 Extracted |
| 5. Edge Ingress | Outbound QUIC Handshake to Cloudflare Anycast | Cloudflare cloudflared | 3 mins | Zero DNS or IP Changes |
| Total MTTR | Full Production Cluster Recovery | End-to-End Pipeline | 86 mins | 100% Production Workloads Restored |
Systems Engineering Lessons (What to Do With This)
Disaster recovery under pressure reveals every latent flaw in your architecture. Reflecting on this recovery alongside our previous experiments in agent-driven security, four durable rules emerged:
- Decouple your backup media physically from your hypervisor chassis. If the PBS datastore had been hosted on an internal RAID array inside the stolen rack server, this story would have been an obituary. The single external USB drive was the sole bridge between total loss and full recovery. (Our immediate next priority is off-site chunk replication to Backblaze B2 so even a single physical drive is never a single point of failure again).
- Recreate network topology virtually rather than refactoring in a crisis. The temptation during an outage is to make things "just work" by dumping workloads onto whatever flat subnet is available. Rebuilding the isolated
10.0.10.0/24subnet on an internal bridge saved hours of troubleshooting and kept firewall security completely intact. - Follow enterprise standards over default convenience (WinNAT over Default Switch). Hyper-V's
Default Switchwill randomly renumber your server subnets on reboot. A dedicated internal switch with persistent kernel WinNAT provides static, deterministic reliability that survives reboots. - Enforce architectural separation of concerns (Dedicated PBS VM). Resisting the urge to co-install PBS directly on the hypervisor host eliminated memory contention, prevented kernel panic deadlocks, and gave both hypervisor and backup storage independent lifecycles.
- Outbound-only tunnels turn infrastructure into portable workloads. In traditional hosting, moving a server between physical networks requires DNS record changes, public IP re-allocation, and router port-forwarding. With Cloudflare Tunnel, an origin server can live in an enterprise rack, move to a nested desktop VM, and re-anchor itself to the global edge without the internet ever knowing the difference.
The physical rack server is gone. But the systems are alive.
Have you ever tested a bare-metal recovery without your primary hypervisor hardware? If your main server disappeared tonight, would you be able to reassemble your deduplicated chunk stores from a single cold disk? Tell me where your recovery seams would break.
Table of Contents

About Eddy Kawira
Infrastructure Engineer & AI Systems Architect with 20+ years across IT systems, data center operations, and cloud architecture. Experience ranges from high-scale AWS data center deployments (Trainium2) and enterprise Azure Virtual Desktop migrations to building open-source AI agent tooling (ClawHub) used by 10,000+ developers. Runs a battle-tested hybrid Proxmox VE and Hyper-V homelab focused on reliability, deep observability, and safe automation.
View all posts by Eddy Kawira →